Software · Open source · 2026
VoiceSynth Studio
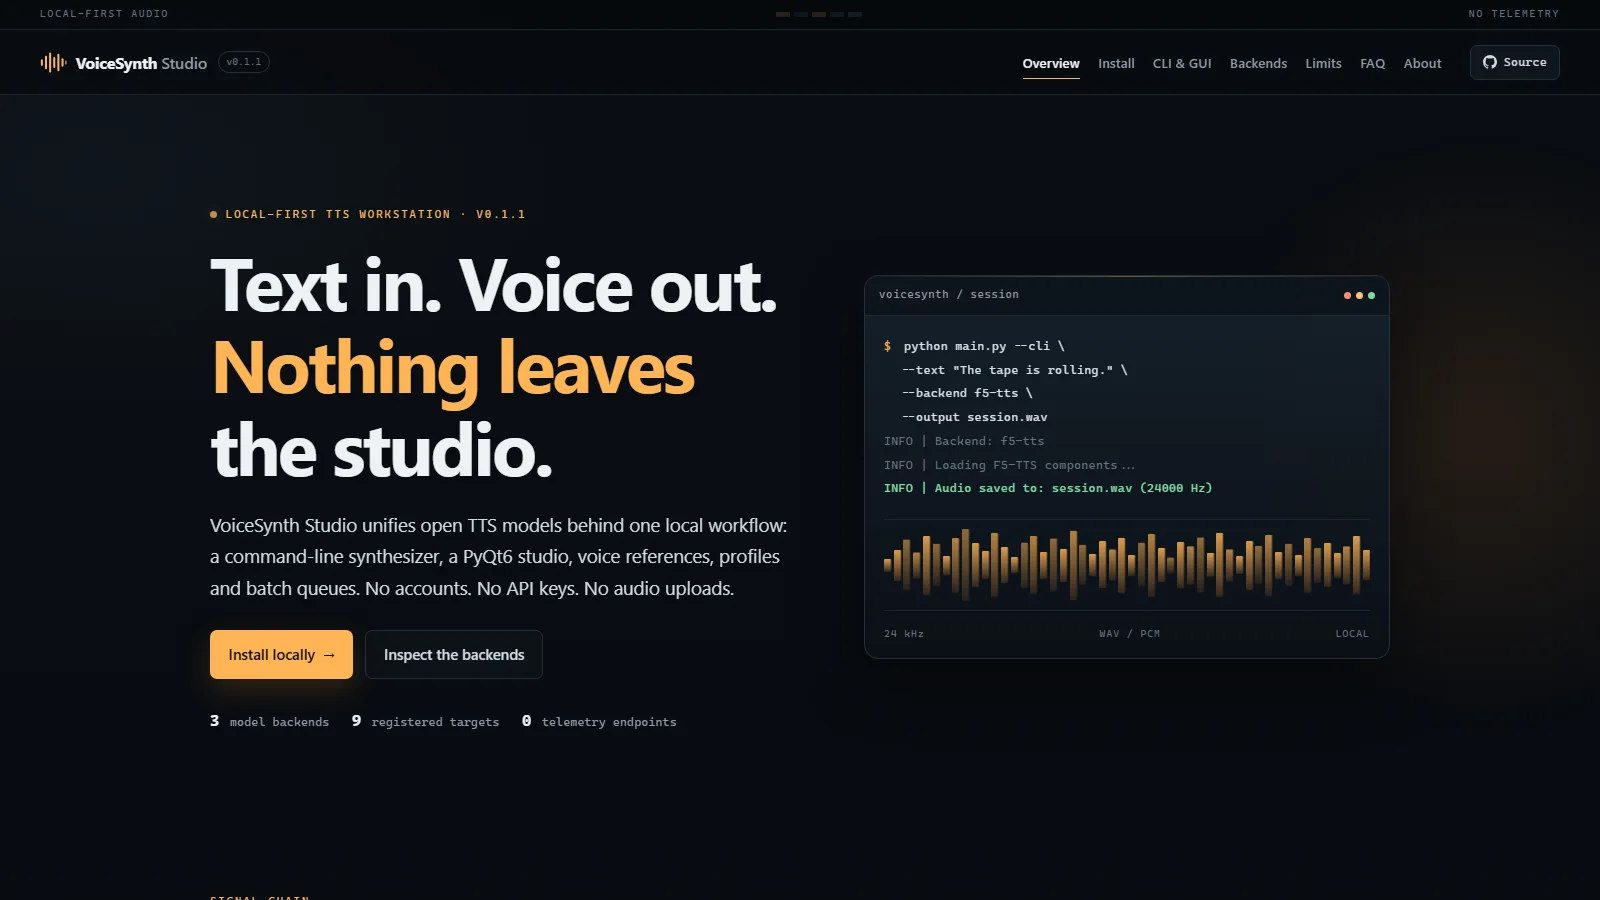
A local-first text-to-speech workstation: a unified backend layer, voice profiles, a batch queue and a desktop studio, running on your own machine with no cloud API and no telemetry.
Loading live site…
- 1
- backend fully implemented, F5-TTS
- 0
- cloud calls, accounts or telemetry
Cloud text-to-speech charges by the character and keeps your text. This project runs open models locally instead: one contract that several backends implement, a manager that resolves device and precision, a command line for one-shot synthesis, and a desktop studio for everything else.
What we built
- A shared backend contract and registry, so a new engine is added in one place
- F5-TTS implemented as the default backend, with zero-shot reference audio, sampler controls and adapters
- Voice profiles stored in SQLite, with sample quality scoring, transcription of reference clips and import/export
- A batch queue with pause, resume and cancel, plus GPU memory monitoring and four presets
- Text chunking with crossfade stitching for long passages, and a memory manager for large models
- An honest backend matrix on the site: what is implemented is listed as implemented, and what is a scaffold is listed as a scaffold
The models are upstream projects; this work is the layer that makes them usable together. No account, no telemetry, no network traffic except the first weight download.